🚀 Admissions Open: Next AI & Data Engineering Cohort starts soon. Limited seats per batch.
Trusted by 20,000+ Happy Learners

Building a Brighter Tomorrow
With Smarter Learning

Learn from trusted experts with interactive courses designed to fit your schedule, match your goals, and support your growth at every step.
Interactive classroom learning
Interactive Learning
Learning on the go and flexible remote study
Flexible Learning
Peer programming and code reviews
Peer Collaboration
Active student group discussions and workshops
Expert Mentorship
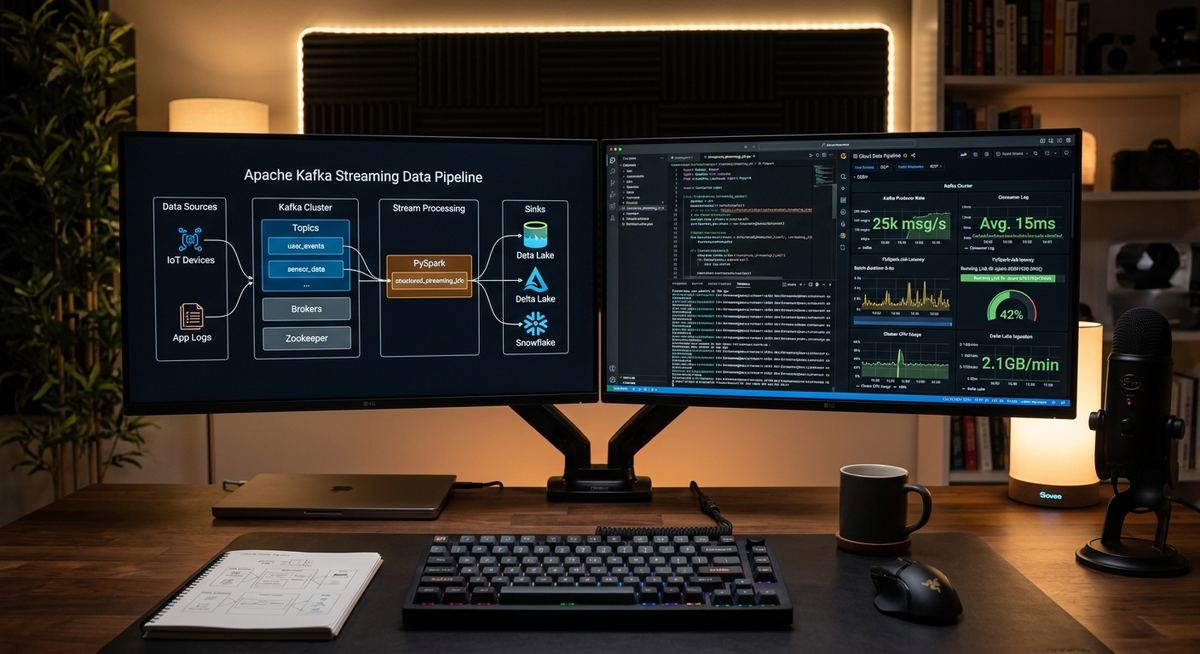
Focused software engineering capstone
Industry Capstones
Admissions Open for Next AI Cohort
🎯 Get Yourself Trained & Placed

Modern AI & Data Engineering

Master distributed data pipelines, PySpark, Airflow, Vector Databases, and LLM infrastructure. Hands-on capstones, 1-on-1 mentorship, and direct placement support.

100% Industry-Aligned Curricula
1-on-1 Technical Mock Interviews
Live Production Capstones
Support, without the wait

Ask first. Connect with a counsellor when needed.

One simple support journey from a quick answer to a trackable concern.

01

Ask your question

Type a question about courses, fees, admission, or placements.

02

Get instant guidance

The assistant replies immediately using verified academy information.

03

Escalate when needed

Raise a concern with chat context for the counsellor support queue.

100%
Production Project Focus
1-on-1
Mentorship & Code Reviews
20+
Hands-On DE & AI Modules
Direct
Placement Panel Referrals
Built for Career Transition

Why Choose TWS Academy?

We eliminate the gap between theoretical textbook coding and real-world enterprise engineering standards.

AI-Native Data Curriculum
Next-Gen Curriculum

AI-Native Data Curriculum

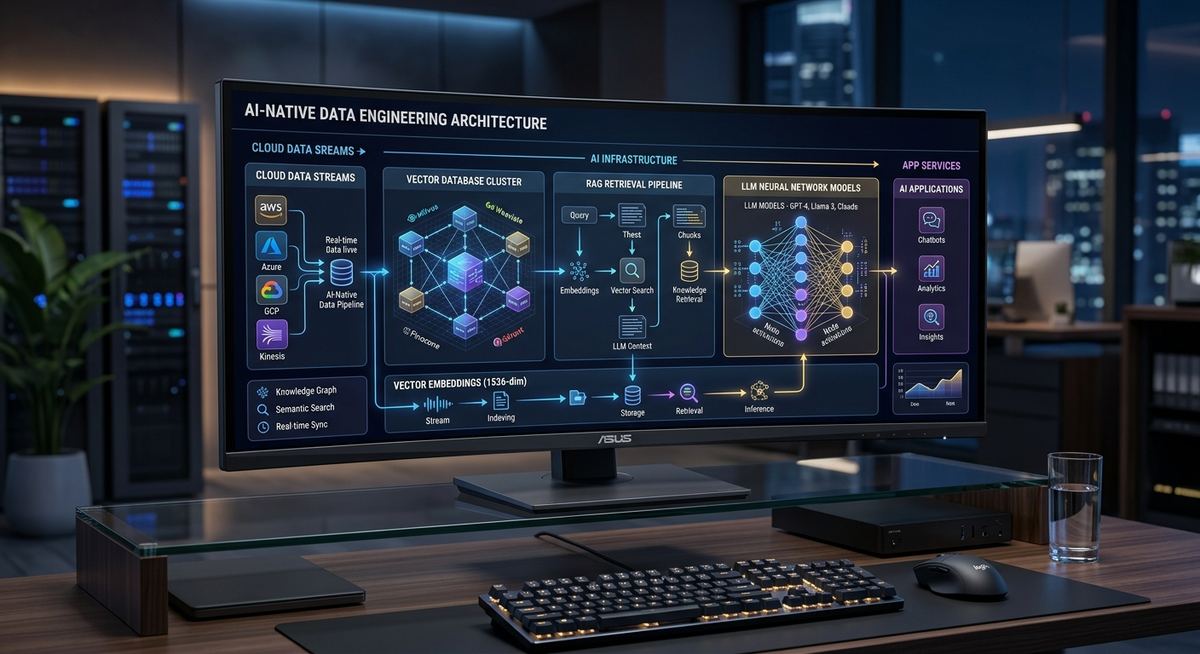
Learn Data Engineering natively integrated with Generative AI infrastructure, vector search engines, RAG orchestration, and automated LLM pipelines.

  • Vector Search & Semantic Retrieval Architectures
  • Autonomous LLM Agent Orchestration with LangChain
  • Scalable Prompt & Model Deployment Pipelines
Real Engineering

Production-Grade Capstones

Build live data streaming engines with Apache Kafka, PySpark, Airflow DAGs, and Snowflake on AWS/GCP — real portfolios that impress tech directors.

  • Real-Time Streaming Pipelines with Kafka & Flink
  • Batch & Delta Lake Processing via PySpark
  • Enterprise Airflow DAGs & Cloud Data Warehousing
Production-Grade Capstones
Direct Placement Cell & Corporate Network
Career Transition

Direct Placement Cell

1-on-1 mock interviews with active tech hiring managers, resume transformation, communication skill training, and corporate referral support.

  • Active Hiring Manager Technical Mocks
  • Direct Corporate Referral Network Access
  • High-Impact Resume & Github Portfolio Revamp
Structured Curricula

Featured Training Programs

View All Courses
Step-by-Step Journey

Your Transformation Roadmap

How we guide you from enrollment to landing your target engineering job.

01
Step 01

Foundations & Core Engineering

Master Advanced SQL, Python OOP, Linux environment scripting, and relational data modeling with hands-on daily coding drills.

02
Step 02

Distributed Big Data & Warehousing

Scale pipeline processing with PySpark, partition big datasets, deploy Airflow DAGs, and structure cloud warehouses on Snowflake/BigQuery.

03
Step 03

Generative AI & Vector Search Infrastructure

Integrate Vector Databases (Pinecone, Milvus), chunk unstructured text/audio data, build RAG pipelines, and deploy LLM microservices.

04
Step 04

Production Capstone & Portfolio Review

Architect an end-to-end cloud production system, document GitHub repository clean code standards, and complete mentor code reviews.

05
Step 05

Mock Interview Panel & Placement Referral

Participate in 1-on-1 mock technical interviews with tech leads, refine your communication skills, and enter our corporate referral pipeline.

Real Production Experience

Practical Capstone Projects

No toy datasets. You build enterprise-ready architectures that prove your capability during interviews.

Real-Time Streaming & Analytics

Real-Time Transaction Fraud Detection Pipeline

High-throughput event streaming engine that ingests thousands of transactions per second, evaluates fraud scores via Spark Structured Streaming, and alerts analysts.

Key Features:
  • Sub-second transaction ingestion & validation
  • Distributed windowed analytics in Spark
  • Automated alert triggers for suspicious patterns
Apache KafkaPySparkDockerPostgreSQLGrafana
Generative AI Infrastructure

Enterprise Knowledge Graph & Vector RAG Pipeline

Unstructured document pipeline that parses thousands of PDF reports, generates semantic embeddings, and powers a context-aware internal Q&A agent.

Key Features:
  • Automated PDF parsing & semantic chunking
  • Hybrid dense–sparse vector search
  • Hallucination prevention & source citation
PythonVector DBLangChainFastAPIDocker
Data Warehousing & Orchestration

Automated Multi-Cloud Warehouse ETL Orchestration

Production Airflow DAG network ingesting REST API data, transforming raw JSON into star-schema models, and loading into a cloud warehouse with quality checks.

Key Features:
  • SCD Type 2 history tracking for dimensions
  • Automated data validation rules
  • CI/CD DAG deployment
Apache AirflowSnowflakedbtPythonAWS S3
Enquire Now

Let's find the right learning path for you

Share a few details and our admissions team can help you understand program fit, learning format, and the next available cohort.

  • Personalised guidanceDiscuss your background and career direction
  • Clear program comparisonCompare AI and Data Engineering learning tracks
  • Simple next stepsUnderstand curriculum, format and admissions

Your details are secure and used only to respond to this enquiry.
Quick enquiry

Speak with admissions

Typically responds within one business day

Start Today

Take the First Step Toward Your New Tech Career

Join our upcoming Data Engineering & AI batch. Speak with an admissions counsellor to review your profile and select the optimal learning mode.